Self-Hosted LLM Cost: What Revolut's 90% Saving Leaves Out
Revolut says self-hosting GLM models cut its AI coding bill to a tenth. What that figure covers, what it leaves out and what to ask before you host a model.
A self-hosted LLM is a large language model that a company runs on computers it owns or rents, instead of sending requests to a vendor’s hosted service, so the cost shifts from a charge per token, a small unit of text, to machines and the people who run them.
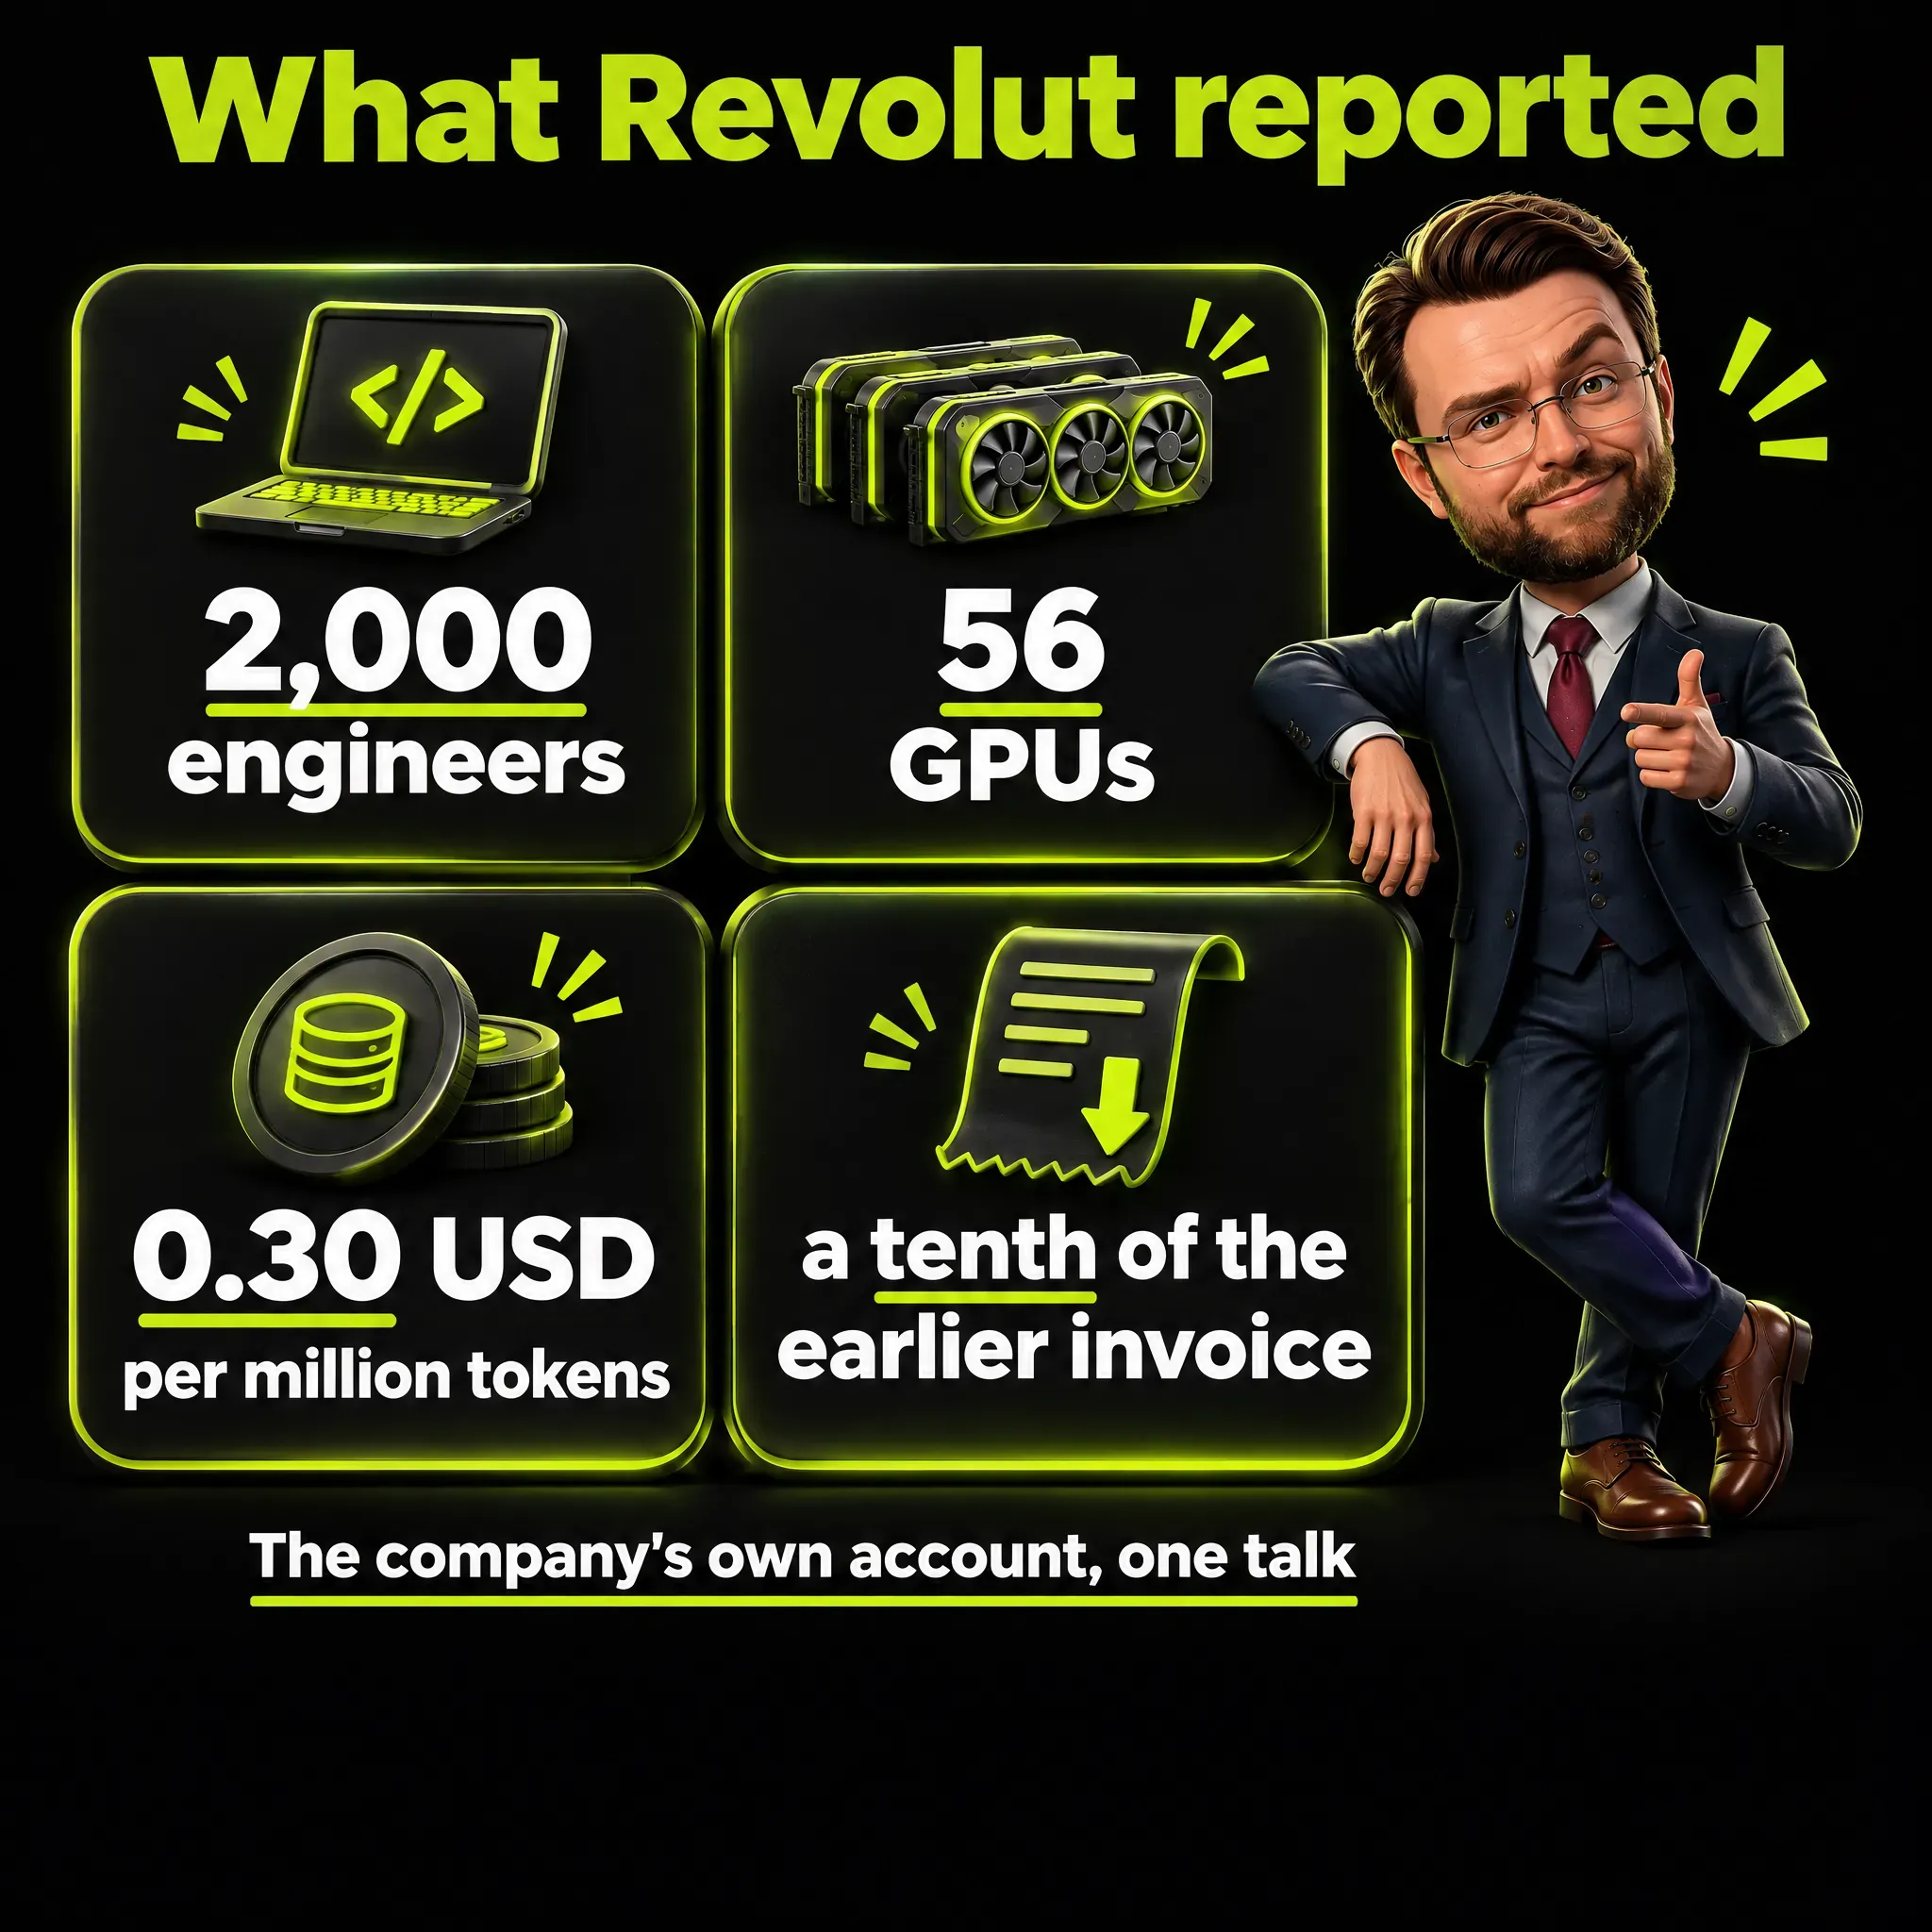
In early November 2026, headlines said that Revolut, a digital bank in Europe, had cut its AI coding costs by 90 percent, or ten times, by running Z.ai’s GLM models on dedicated GPUs. A GPU is the kind of chip that runs AI models, and running a model to answer requests is called inference. The numbers come from a talk by David Abitbol, Revolut’s ops and infrastructure lead, at the AI Engineer conference in New York.
I work in marketing and use AI models every working day, mostly local ones trained for my own needs, so I read this as a user of AI tools and claim no engineering expertise. Before a figure like this reaches a budget meeting, I want to know what is inside it.
This article takes the claim apart and ends with questions to ask before anyone hosts a model.
It covers cost and control and gives no legal advice; geopolitics stays out of it. The price lists and the three ways of running a GLM model are in my article on Chinese AI models for business.
Key Takeaways
- No source gives a price for self-hosting that you can copy. The best-documented case is Revolut’s, and the conference page says its figures “describe Revolut’s deployment and utilization, not a portable price for any self-hosted model”.
- The 90% compares two invoices for one company’s workload. Revolut says its spend is around a tenth of its earlier Anthropic and OpenAI invoice, which is a narrower claim than a 90% fall in everything AI costs the company.
- The cost around the GPUs is missing from the headline. Red Hot Cyber writes that the saving excludes cloud, personnel and monitoring costs. I found no figure for any of them, and no mention of that exclusion, in the talk or in The Register.
- My reading is that the price per token depends on how busy the machines are. On the same 56 GPUs, Revolut reports 76% more requests handled each second and an 88% shorter wait for the first word of an answer after tuning.
- Hosting adds controls that someone has to run. Revolut pairs cheaper inference with a sandbox, approval rules and detailed logs, and the conference page says self-hosting leaves the bank responsible for the lower inference costs, the sandbox rules and the telemetry alike.
- For a marketing team, my suggestion is to start with a hosted model. No source tests this, and the questions at the end of this article are how I would test it.
What Revolut Reported, and Who Says What
Everything below traces to three kinds of source. The first is the talk itself, which I read through the AI Engineer conference’s written summary of it, called the conference page below, and through its transcript. The second is the journalism that retold it, mainly The Register and Red Hot Cyber.
The third is my own arithmetic on their numbers. I keep the three apart because each retelling changed the claim a little, and the talk is a company describing its own setup.
Four terms first, because the table uses them:
- Token: the small unit of text a model reads and writes, often a short word or a piece of a longer one.
- Blended cost: one average price over everything that goes in and comes out.
- First token: the first piece of an answer to appear on screen.
- Coding time and lead time: the hours an engineer spends writing code, and the days from picking up a feature to having it ready to deploy.
| Item | Figure | Source |
|---|---|---|
| Users | About 2,000 engineers | The talk |
| Hardware | 56 Nvidia B200 GPUs serving GLM-5.3 | The talk, The Register |
| Cost per token | A blended cost near 0.30 dollars per million tokens | The talk (conference page) |
| Spend | Around a tenth of the earlier Anthropic and OpenAI invoice | The talk (conference page) |
| Effect on work | About 60% better coding time, 70% better lead time | The talk, with a caveat |
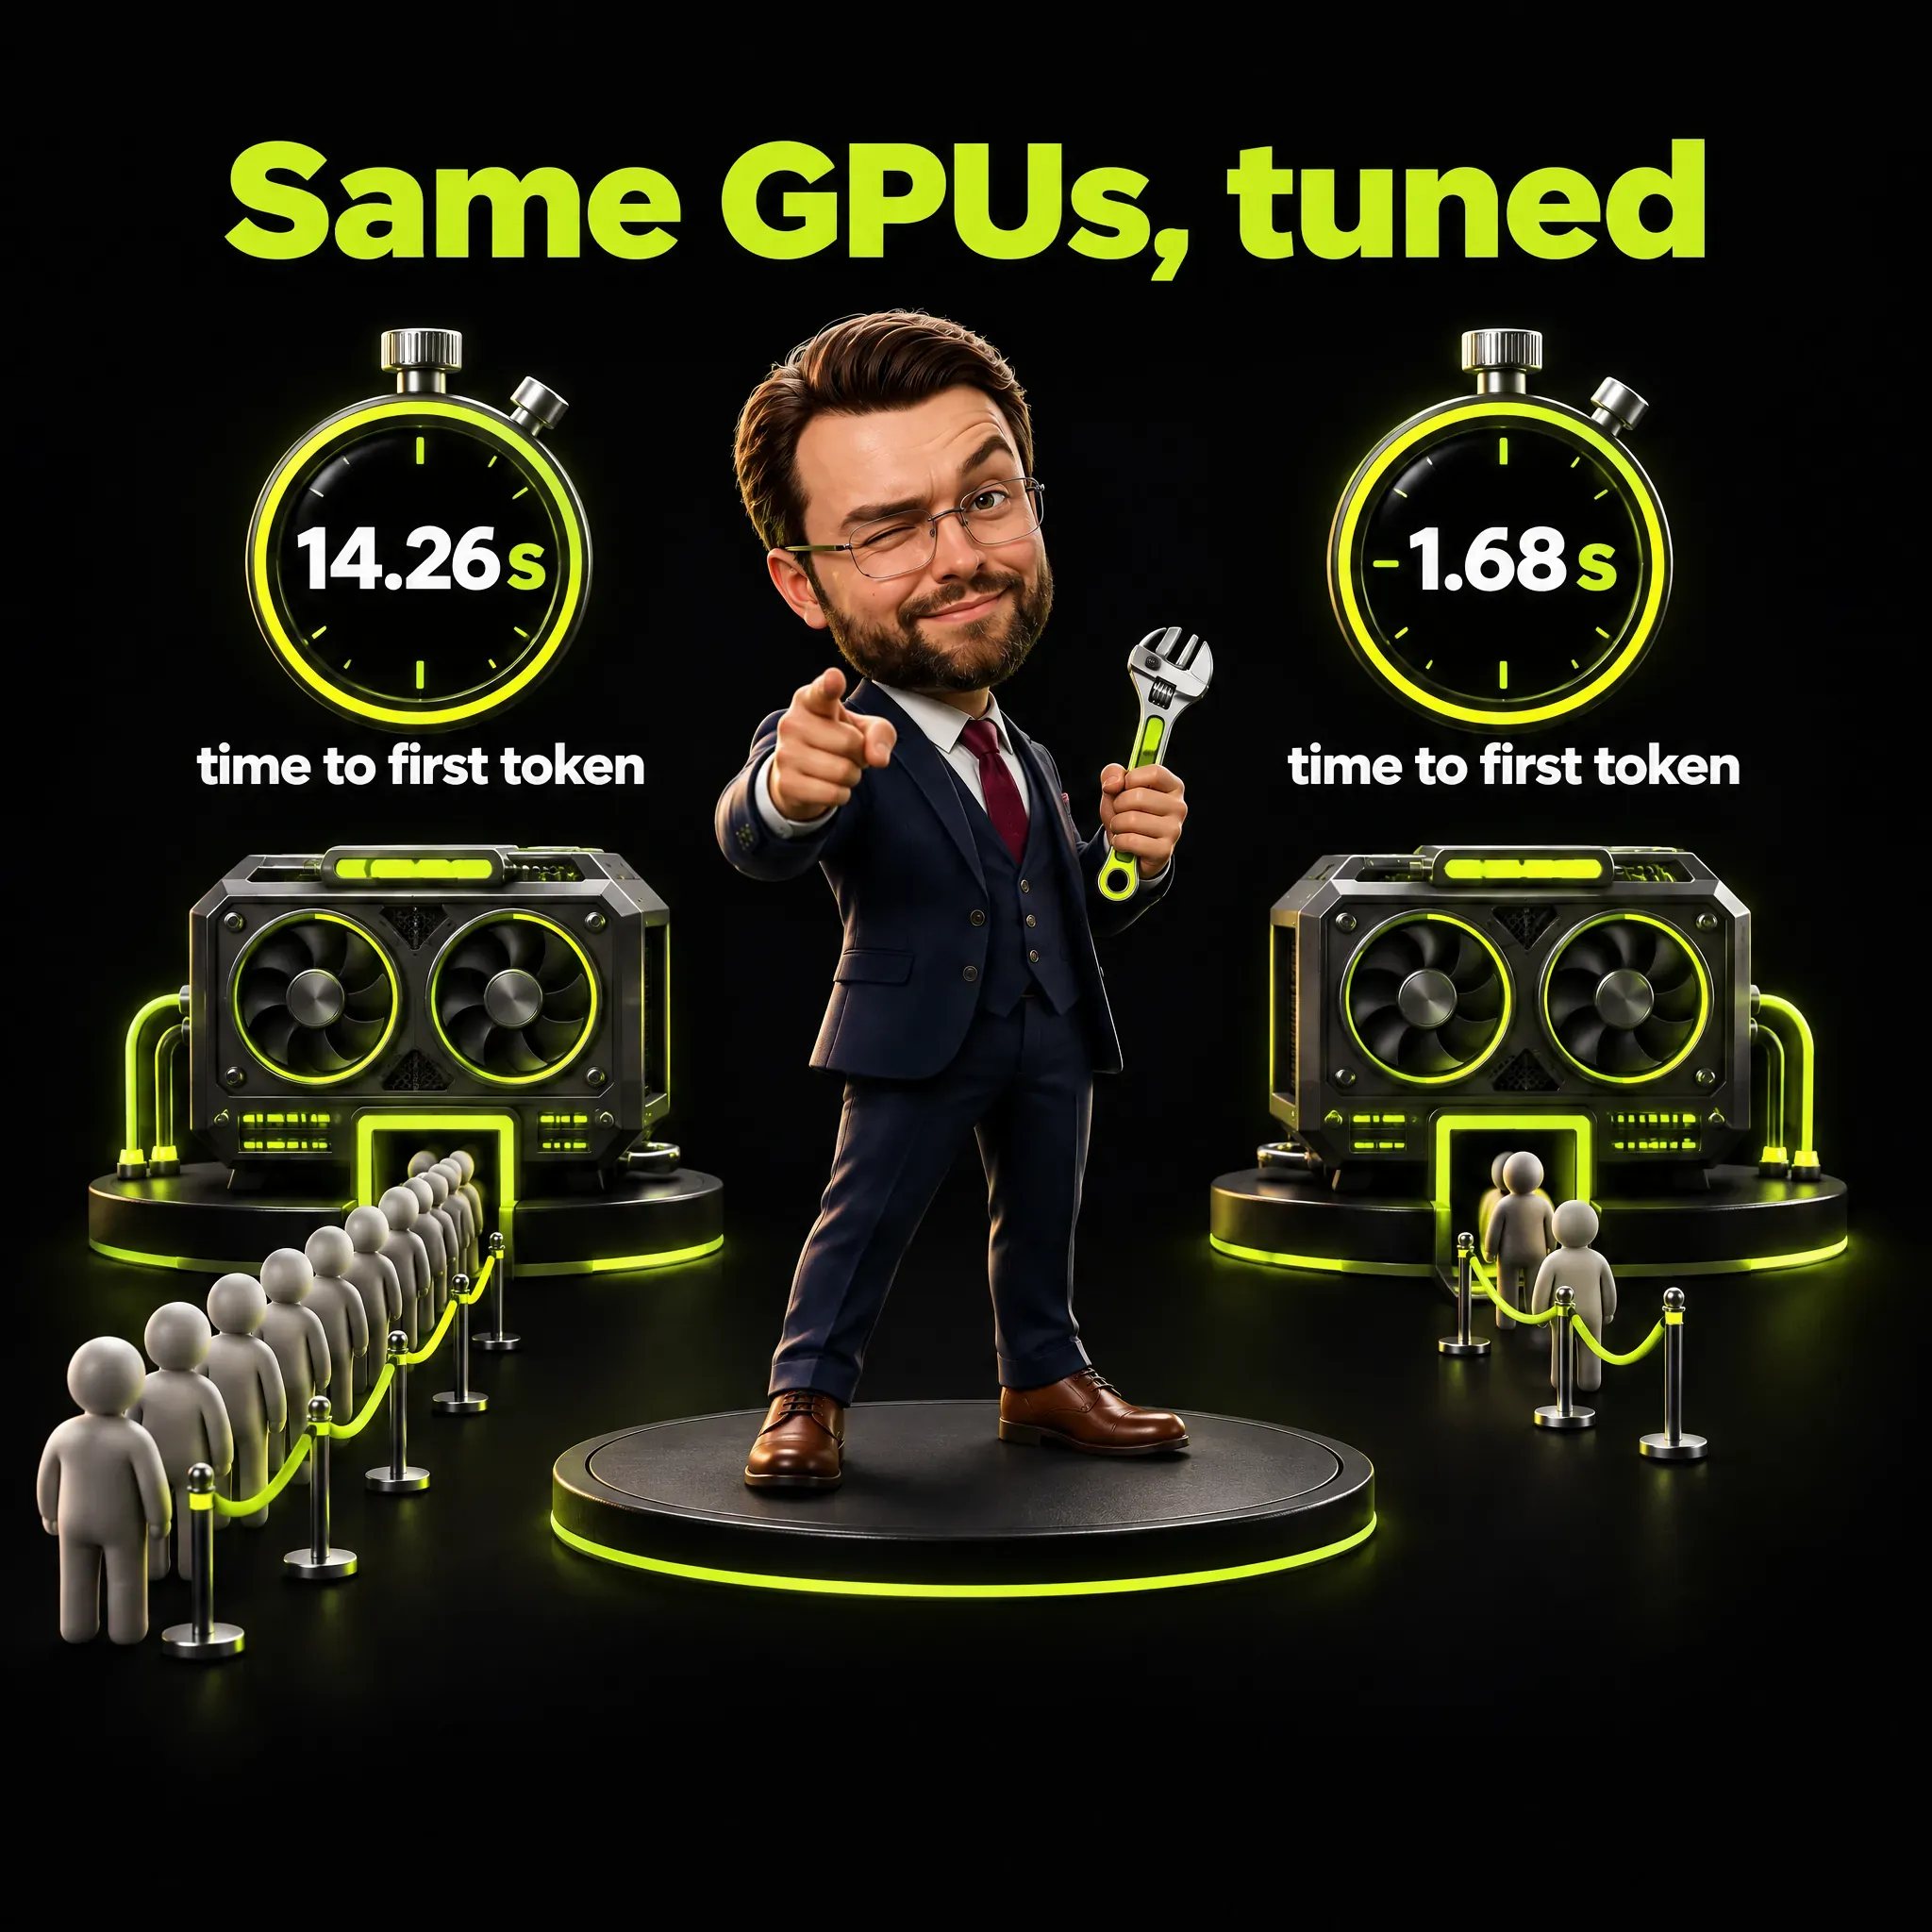
| Wait for an answer | First token in 14.26 seconds, then 1.68 seconds, on the same GPUs | Slide described on the conference page |
| Targets | First token under 3 seconds, about 200 tokens a second | The talk |
The 60% and 70% improvements need a caveat that the conference page states itself: “The internal comparison does not isolate the model change from other causes.” So the chart shows what happened at Revolut over the months of the rollout, and it does not show what the model alone did. Red Hot Cyber names one of the other factors: the removal of token limits.
The talk gives the 0.30 dollars per million tokens for “GLM” without naming a version, while The Register ties it to the earlier GLM-5.1 setup, so I would not attach the number to one model. Revolut has 80 million customers, according to Abitbol, but this workload is about 2,000 engineers.
Three Claims, One Number
The same arithmetic produced three different sentences, and they are not equally safe to repeat. Ten times cheaper and 90 percent less are the same ratio; they differ in what the ratio is said to cover.
The first claim is Abitbol’s own, as the conference page summarizes it: Revolut’s spend is around a tenth of its earlier Anthropic and OpenAI invoice. That compares what one company paid vendors with what it pays now for one kind of work, coding by about 2,000 engineers.
Abitbol also says that when Revolut first rolled out Claude Code, some engineers spent “a thousand a month, 10,000 a month with not so much ROI”, in dollars according to The Register’s printed quote, so the company launched it “with strict budget limits”. The earlier invoice therefore covers rationed use and the current one covers use that engineers can make without watching the meter, a comparison of two ways of working.
The second is The Register’s headline, which says Revolut slashed AI coding costs 10x “by cutting out Claude and going self-hosted”. The body is more careful in places: it says that GLM “hasn’t replaced GPT or Claude entirely”, and it quotes Abitbol saying “the frontier is the exception”. Frontier here means the most capable models from the large vendors, and the conference page agrees that such services stay available for exceptions.
The body also states the ratio differently from the talk. It says that at 0.30 dollars per million input and output tokens, self-hosting GLM-5.1 cost about a tenth of using Codex or Claude Code, the coding agents from OpenAI and Anthropic. My reading is that this sets a per-token cost against a product, which differs from a comparison of two invoices.
The third is Red Hot Cyber’s, which titles its piece on the 90% and then qualifies it. It writes that “The 90% savings exclude cloud, personnel and monitoring costs, and depend on careful optimisation”. It adds that smaller companies, “lacking Revolut’s scale and infrastructure team”, may not achieve the same result.
Where the number comes from: Revolut’s comparison of its earlier invoice with its current spend, presented in the talk. What it means: for that workload, at that volume and with that tuning, the bill for AI coding is about a tenth of what it was. What changes: the figure tells you how much smaller one invoice became, and it does not tell you how much smaller the total cost of the operation became.
I found no breakdown of cloud, staff or monitoring costs on the conference page, in the transcript or in The Register. Red Hot Cyber states the exclusion without giving numbers either, and the talk’s own wording, “our invoice” and “you can get your GPUs there”, leaves open whether the tenth already includes a bill for rented GPUs. I treat the exclusion as Red Hot Cyber’s claim and as a limit of the figure.
Why a Token Price Cannot Be Compared Without the Mix
Z.ai’s list prices show why a blended number needs its mix. In dollars per million tokens, GLM-5.3 input costs 1.40, cached input costs 0.26 and output costs 4.40. Cached input is text the system has already processed and bills at a lower rate.
Coding agents send much of the same text again at every step, so cached input dominates their traffic. Z.ai’s Coding Plan page, its subscription for coding tools, assumes a 95% cache-hit rate, meaning 95 of every 100 input tokens are text already processed. Here is arithmetic on those two sources: 0.95 x 0.26 + 0.05 x 1.40 comes to about 0.32 dollars per million input tokens at list price.
That sits close to Revolut’s blended 0.30, and I draw no conclusion from it. The sources do not give Revolut’s mix of input, cached input and output, and output tokens cost 4.40 on Z.ai’s list. Abitbol does tell his audience to check that the cache hit for a coding workload “needs to be above 90%”, and a blended figure of 0.30 could come from many different mixes.
When someone quotes a cost per million tokens for a hosted setup, I would ask three things: whether it covers input, output or both, what share of the input came from cache, and whether it counts only the GPUs. Without those answers the number cannot be set against a vendor’s price list, which is why I read Revolut’s comparison as one between two invoices.
The full price list is in my guide to Chinese AI models for business. For where model costs sit among a team’s other tools, I use the framework in my marketing tech stack for 2026.
Why the Price per Token Depends on How Busy the Machines Are
Abitbol’s talk is about “self-hosting open source model on dedicated GPU”, which means machines reserved for Revolut’s own use. As I read it, reserved machines cost the same whether they answer one request or a thousand. The price per token is therefore the fixed bill divided by the number of tokens the machines process.
An invented example with round numbers, not Revolut’s: say the machines cost 100 units a month. If they process 100 million tokens, each million costs 1 unit. If tuning lets the same machines process 500 million, each million costs 0.2 units and the bill has not changed.
Revolut does not put its savings this way, but its tuning chart fits this mechanism. Abitbol warns that loading the weights onto GPUs and starting inference, the step where the model answers requests, gives “terrible performance” without that tuning. The team tuned its serving system against its actual demand, and its chart holds the GPU count constant from April to August.
The slide, as the conference page describes it, reports 76% higher requests per second and an 88% reduction in time to first token, from 14.26 seconds during migration to 1.68 seconds in the stable setup. Time to first token is the wait between sending a request and seeing the first word of the answer. By my arithmetic, the wait became about 8.5 times shorter.
Abitbol’s targets are concrete. He aims for “a sub-3 second time to first token” and says “as soon as you exceed 5 seconds, my Slack inbox starts to blow up”. His advice is to “resist scaling”, meaning to tune the existing GPUs before buying more.
Abitbol says engineers who connect after 5 pm can get 800 tokens a second, against the 200 that the conference page calls adequate for interactive work. My reading is that evening demand is lower, so the same machines answer faster, and that idle evening capacity is paid for anyway. For a team with a handful of users, the same fixed bill is spread over far fewer tokens.
What It Takes to Run One, in Plain Words
A GLM-class model needs data-center hardware. The Register reports that GLM-5.1 has roughly 754 billion parameters, with 40 billion activated for each token it generates, and that it needs about 380 GB of GPU memory to hold its weights. Parameters are the numbers a model learned during training, and weights are the files that store them.
Each user’s open conversation takes memory on top of that. The Register puts it at another 6 to 26 GB per user, depending on precision. The GLM-5.3 page on Hugging Face, the public library where such models are published, lists 753 billion parameters, which is the figure I use for the current model.
These are the decisions the talk and The Register describe, in the order a non-engineer can follow:
- Context size. The context window is how much text the model holds in view at once, and it competes with other users’ requests for GPU memory. Abitbol says “long context is a scam”: the model can serve a million tokens, but 256,000 is what his engineers need.
- Storing the weights more compactly. Quantization means storing the numbers with fewer digits to save memory, and Revolut favors a 4-bit format on its B200 GPUs, a current Nvidia data-center chip.
- Spreading the model across GPUs. The conference page notes that fitting the weights across four GPUs may leave too little memory for the cache of text already processed, so an eight-way split can perform better.
- Sending some jobs elsewhere. The GLM model Revolut serves for coding handles text only, so Revolut uses a router that sends image requests to Gemini or GPT Luna while code generation stays on GLM.
A per-token price hides these choices about memory, speed and routing. The cost of a self-hosted model includes the skill to make them, and Revolut kept paying vendors for the jobs the model cannot do.
The Costs Nobody Published
Here is every cost line I would want filled in before comparing a self-hosted setup with a vendor’s price. “Not available” means I found no number in any source I read, and I did not fill the gap with an estimate.
| Cost line | What the sources say | Figure |
|---|---|---|
| The GPUs, bought or rented | 56 B200 GPUs serve GLM-5.3 | Not available |
| Cloud | Red Hot Cyber says the 90% excludes cloud costs | Not available |
| The people who run it | Red Hot Cyber says the 90% excludes personnel; smaller firms may lack an infrastructure team | Not available |
| Monitoring and logs | Red Hot Cyber says the 90% excludes monitoring; Abitbol asks for detailed telemetry to investigate incidents | Not available |
| Tuning time | The chart spans April to August on the same GPUs | Hours not available |
| Vendors kept for exceptions | Frontier services stay available; image requests go to Gemini or GPT Luna | Not available |
| Moving from one model to the next | Revolut moved from GLM-5.1 to GLM-5.3 | Not available |
One point stays open. Red Hot Cyber describes the machines as Revolut’s own infrastructure in the United States, while Abitbol says “you can get your GPUs there” in the countries he lists, and speaks of GPU providers that keep no copy of the data by default, which he calls “zero data retention”. I cannot tell from the sources whether the GPUs are bought or rented, and the answer changes the shape of the bill.
My suggestion is to use the table as a form. When someone tells you a saving of 90%, ask them to fill in each line for their own case, or to say which lines the figure leaves out. A saving that survives that exercise is one I would put in a budget.
For the cost that appears after the invoice, the time of the person who checks the output, I compare two Claude tiers in Claude Haiku vs Sonnet for marketing. The method there, running 20 real samples blind, works the same way for a hosted GLM model.
What Cheaper Tokens Change in How People Work
For me the most useful part of the talk is about behavior. The conference page describes what happened under token limits: when tokens feel scarce, engineers save them for a difficult coding task and do not use them across the surrounding work. Revolut’s answer was a flat cost that let engineers delegate more.
Abitbol’s own interpretation is that delays in engineering include the inbox, Jira and Confluence, which are the project-tracking and documentation tools around the code. Cheaper access, on his account, widened which tasks people were willing to hand to the model. The Register quotes him on debugging and ticket work: “When you have unlimited tokens, you’re free to do that.”
That makes the 60% and 70% figures hard to read. Part of the improvement may come from the model, part from engineers using AI for more kinds of work, and the conference page says the comparison does not separate them. I would credit neither the model alone nor self-hosting alone.
For my own field, I can only offer a scenario, and it is invented. Imagine a marketing team that rations an AI agent because each long job costs real money, so it uses the agent for the monthly report and does the daily tagging and checking by hand. If the bill were flat, the same team might hand those small jobs over as well.
No source measures this for marketing. Someone still pays for the machines, and the gain shows up only if the extra work the agent does is good enough to keep after a person has checked it.
Where the Data Goes, and What the Talk Does Not Settle
The conference page makes a plain point: downloading the weights and running them on infrastructure the company selects is a different data path from sending requests to a model developer’s hosted service. On this, Abitbol says the privacy worry about Chinese models concerns calling a dedicated endpoint in China, while taking the weights and putting them “on a US-based service” is a different case. The Register sums up his view as one where on-premises machines, meaning the company’s own servers, or a cloud provider in the same region leave little to worry about, which is the reporter’s wording and not a quote from Abitbol.
He adds that data kept in the countries of what the transcript renders as a “data equivalency framework”, which he lists as the US, the EU, the UK and Israel, is fine, and that inference and GPU providers will have “zero data retention by default”. No source I read checks that claim about providers. These are his statements about Revolut, a bank, and the conference page says they “should not be read as a general determination that a model, region, or sandbox automatically satisfies another organization’s obligations”.
For the maker’s own API, Z.ai’s privacy policy says its services are generally provided from Singapore, and its API addendum contains a no-storage clause. Both are Z.ai’s own statements, and neither has been checked by a third party. I go through both documents in the data section of my article on Chinese AI models.
I am not a lawyer, and this is not legal advice. If personal data such as customer lists or lead exports would go to any model, I would put three questions to the data-protection adviser first: which country, under which contract, with what retention.
Controls Around the Model
Abitbol’s closing message is about control around the model. Revolut sets up a sandbox, which is a fenced area where the coding agent runs, together with approval rules for operations the company does not want to allow. His example is that “you can allow grep but not gradle”: a rule can let the agent search through files and block it from running a build tool.
He says the coding tasks are not treated as autonomous agents, because “they’re always with a human in the loop”, and that the sandbox gives the regulator reassurance on that point. He also says the sandbox protects against misuse by people inside the company. The last requirement is telemetry, meaning detailed logs, so that the team can trace an incident through the system.
On prompt injection, an attack in which text hidden in a document or web page tries to give the agent new orders, Abitbol’s remark is short: “Not so much a thing now, given how smart models are, but always a thing.” That is his opinion in a talk, and in that passage he cites no test for it.
The conference page lists lower inference costs, sandbox rules and telemetry, and closes with “Self-hosting leaves Revolut responsible for all three.”
One more responsibility comes with open weights, the model files that a maker publishes for anyone to download. The refusals built into such a model live in those files, and Anthropic’s report on GLM-5.3 describes removing them with the technique I explain in what abliteration is. The Cloud Security Alliance, an industry security group, restates Anthropic’s figures and recommends treating model weights as sensitive assets.
A marketing team that never hosts a model still needs a sandbox, approval rules and logs once an agent can act on its accounts. The approval step is the one I describe in human-in-the-loop AI verification, and the wider risks are in my piece on AI agent security.
Questions to Ask Before You Host a Model
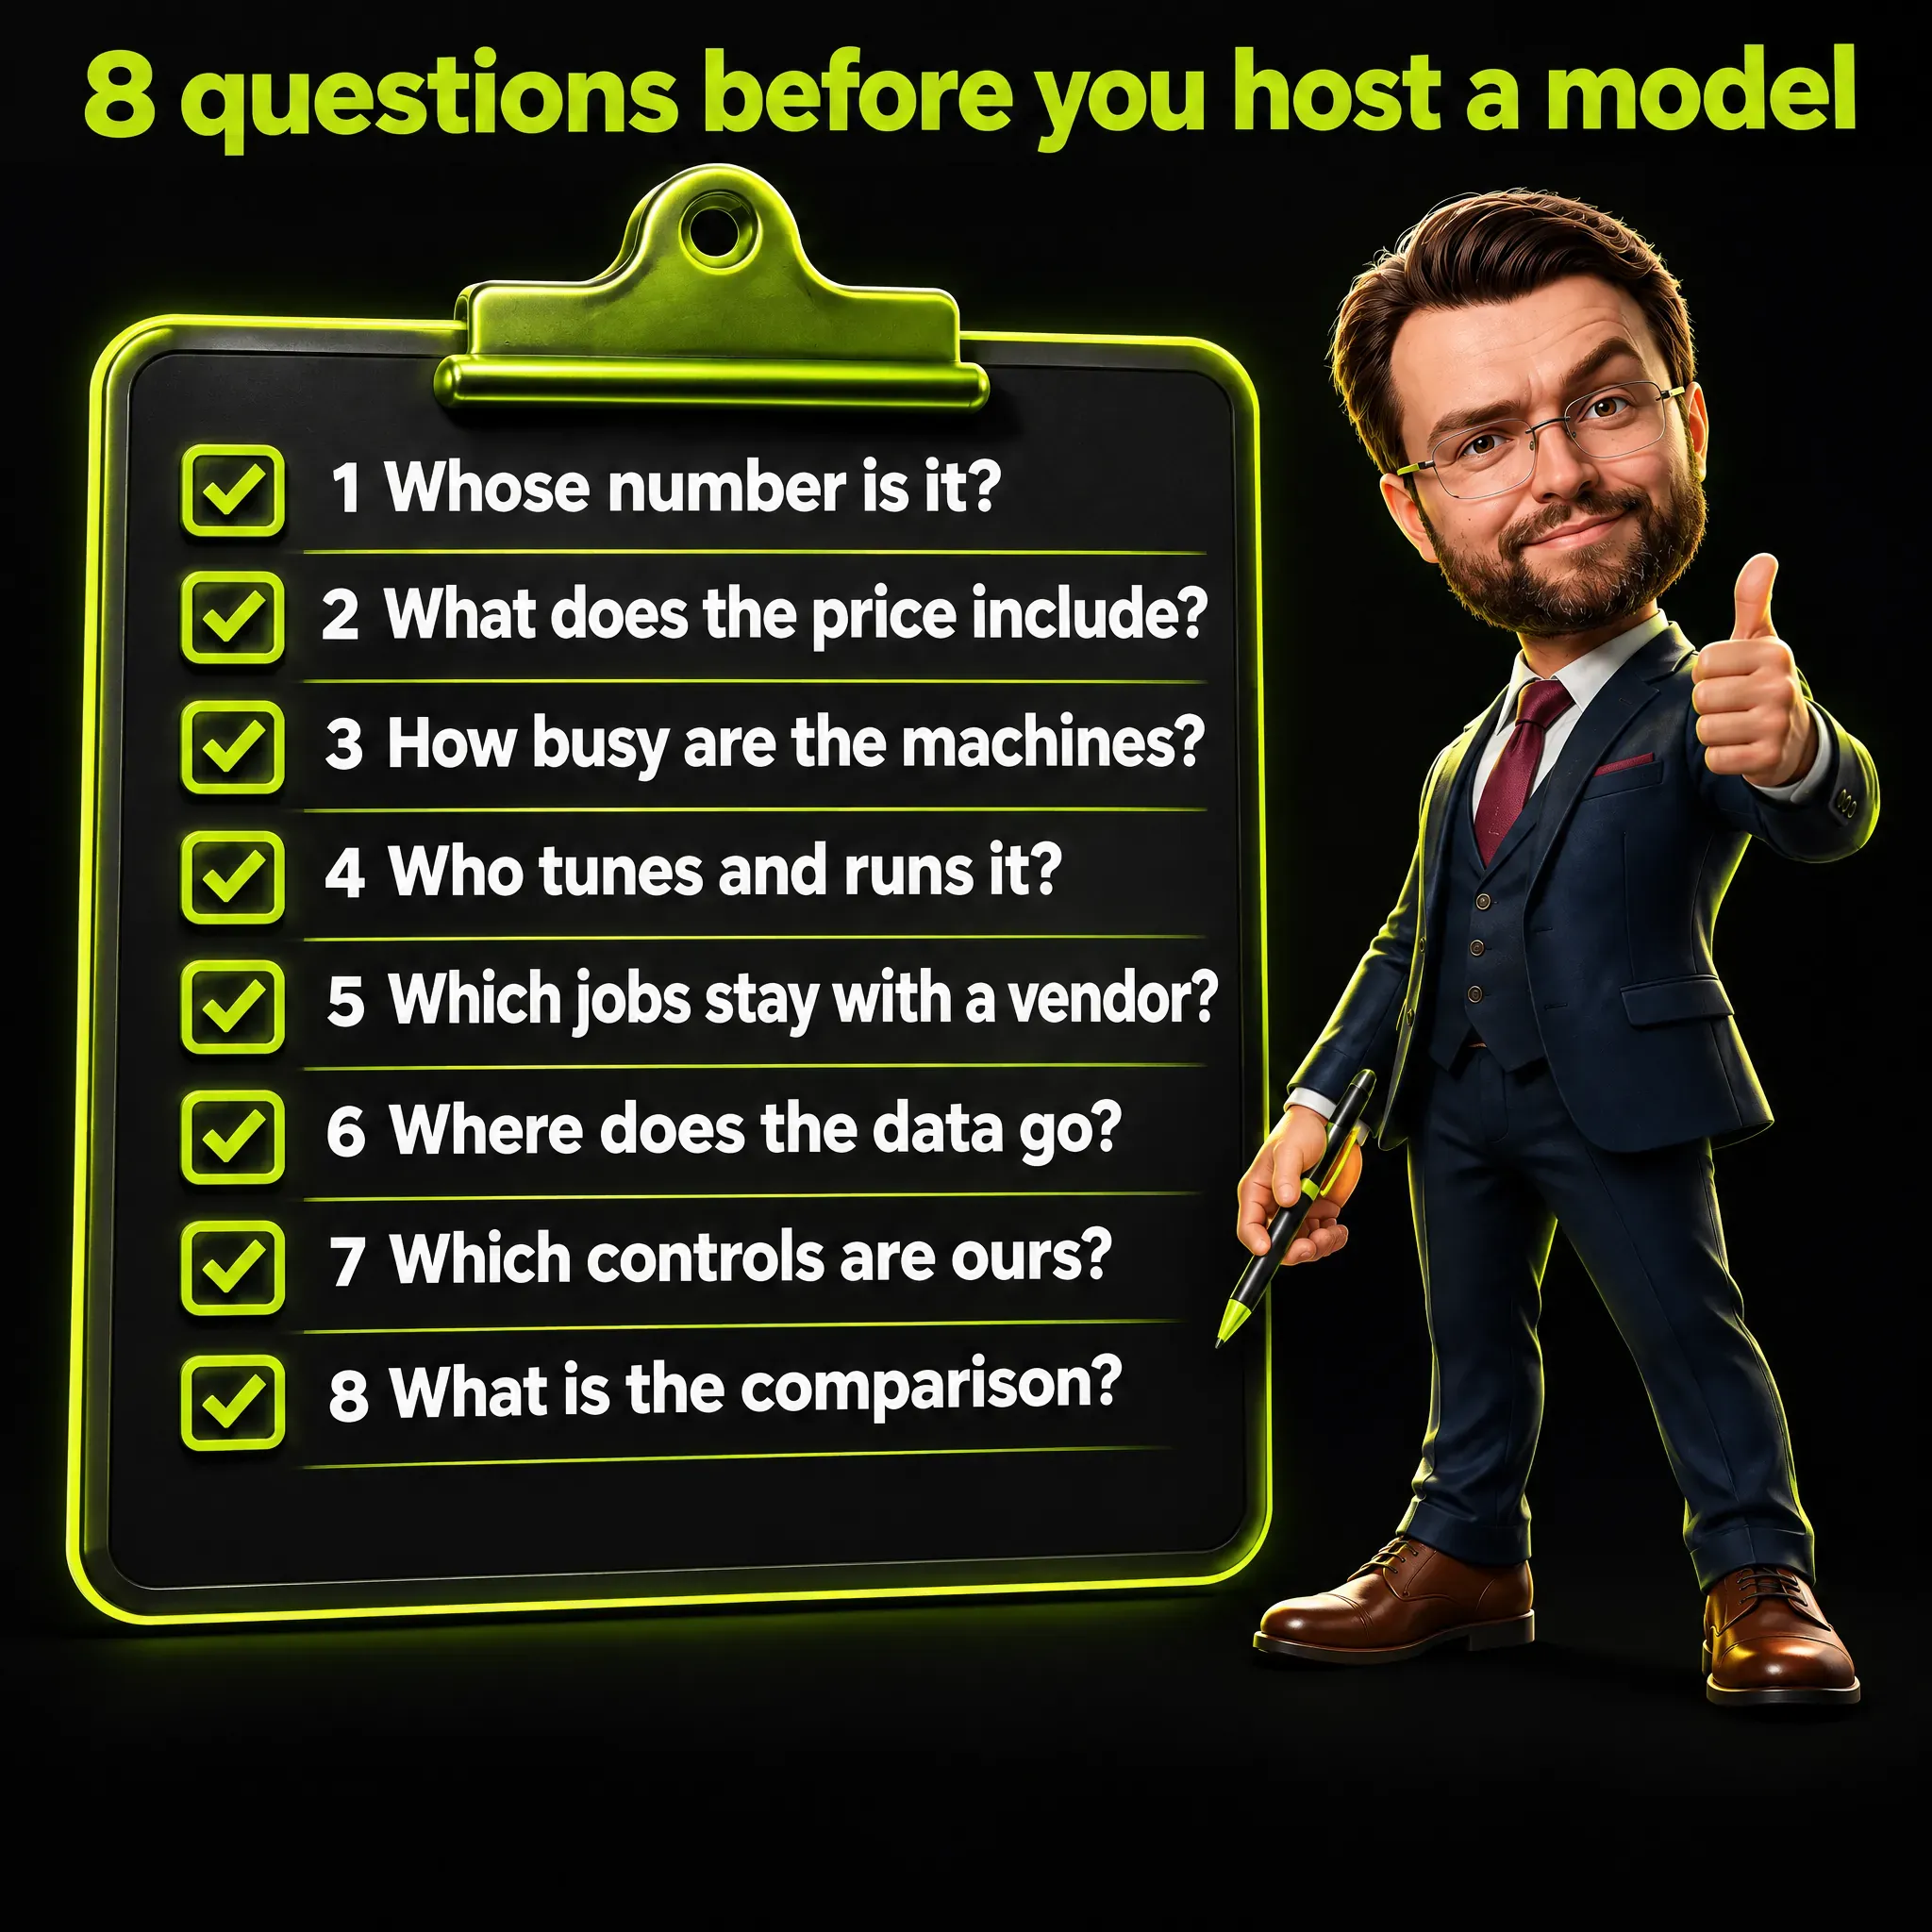
I turned the sections above into eight questions. They are my own checklist and apply whether the claim comes from a conference talk or a vendor’s slide.
| Question | What I would want to see |
|---|---|
| Whose number is it? | The source of the saving, the period and the workload it covers |
| What does “cost per token” include? | Input, output or both, the cache-hit rate, and whether only GPUs are counted |
| How busy will the machines be? | Expected users and requests, since the price per token falls as use rises |
| Who tunes and runs it? | A named team and its hours, since Revolut’s tuning chart spans April to August |
| Which jobs stay with a vendor? | A list of tasks, such as image requests, that still need another model |
| Where does the data go? | The country, the contract and the retention, taken to the data-protection adviser |
| Which controls are ours? | A sandbox, approval rules, logs and a person who owns the weights |
| What is the comparison? | A hosted model on the same task, judged blind on 20 real samples |
If the answers are vague, I treat the saving as a hypothesis. If they are specific and the volume is large, self-hosting becomes a serious option. For a small team, my inference from Revolut’s numbers is that the fixed bill and the need for an infrastructure team are the obstacles.
Frequently Asked Questions
What is a self-hosted LLM?
It is a large language model that a company runs on machines it owns or rents, instead of calling a vendor’s hosted service. The model files have to be available to download, which is why self-hosting usually means an open-weight model, one whose maker publishes those files.
How much does it cost to self-host an LLM?
No source I read gives a portable price. Revolut reports a blended cost near 0.30 dollars per million tokens and a spend of around a tenth of its earlier invoice, using 56 B200 GPUs for about 2,000 engineers. The costs of cloud, staff and monitoring are not published.
Is self-hosting cheaper than paying for an API?
For Revolut, by its own account, it was. In general I cannot say, because the answer depends on volume, how busy the machines are and the cost of the people who run them, and the sources I found describe one case.
Can I run an LLM on my own computer?
Not one of this class. GLM-5.3 has 753 billion parameters according to its Hugging Face page, and The Register puts the weights of the earlier GLM-5.1 at about 380 GB of GPU memory, far beyond a laptop.
What is the difference between open-weight and self-hosted?
Open-weight means the maker publishes the model files. Self-hosted means you run them on machines you control. A third party can also host the open weights for you, which is the second route in my article on Chinese AI models.
Does self-hosting keep my data private?
It changes the path the data takes, which the conference page calls a different data path from a developer’s hosted service. It does not answer legal questions, and it makes the safeguards and the logs your own job, so I would take the data question to the data-protection adviser.
Do I need an infrastructure team?
Red Hot Cyber says smaller companies lacking Revolut’s scale and infrastructure team may not achieve the same result. How large such a team has to be is not available in the sources.
Is a self-hosted LLM worth it for a marketing team?
My view, not a finding: I would first use a hosted model and run the eight questions above. A hosted route keeps the bill variable but avoids the machines, the tuning and the controls that come with them.
My Take
What I take from the Revolut case is a method for reading any saving. A saving of 90% deserves the same questions as any claim in a budget meeting: whose figure, what period, what is inside, and what is left out. Red Hot Cyber answers the last question with cloud, people and monitoring; the talk itself lists no exclusions, and nobody has published those costs.
I also take the behavior change seriously. If an invoice stops rationing the use of AI, people hand it more of the work, and the effect on productivity may be as large as the effect on the bill. That applies to a flat subscription and to hosted models as much as to GPUs of your own.
I would start with a hosted model, measure the real use over a few months, and fill in the cost table above with your own figures. If the volume and the team justify machines of your own, the tuning and the controls are the part to plan first.


