A Second Brain AI Can Actually Read: How I Structure Obsidian for My Agents
How I built a second brain AI that actually retrieves: the exact Obsidian structure that makes Claude read real answers instead of inventing them every time.
Your AI Does Not Know You
Every conversation with an AI starts from zero about you. The model knows everything the internet has published and nothing about your customers, your last three campaigns, or the decision you made this morning. That gap is the whole problem, and I fixed it with a Second Brain AI that can actually read.
You paste in forty pages of context. It nods. Then it invents the one page you forgot to paste, with total confidence. I run AI through my marketing work every day, and I can tell you exactly where this comes from. I wrote the full accounting here. The short version: the model is not broken. The way we hand it our memory is.
The moment that pushed me over the edge was boring. I asked a model about a project I had discussed with it the week before. It answered smoothly, in full sentences, and half of the answer was wrong. It had no memory of the week before, and it was too polite to say so. It guessed, and it sounded sure. That is worse than silence.
So I stopped fixing the prompt and started fixing the structure. I built an Obsidian vault with rules inside it, not only notes inside it. The result is an agent that retrieves real answers instead of guessing at fresh ones. This article is the exact structure, with the numbers from a vault I run every single day.
Key Takeaways
- Your AI starts from zero about you, every time. No amount of prompt tuning fixes that. The fix is a memory the agent can read, not more instructions.
- A second brain ai is a routing problem, not a tooling problem. The work happens in a rules file and a recency index, not in a plugin.
- CLAUDE.md is the file that changes everything. It lives inside the vault, so the agent reads the rules itself instead of being told them by you.
- Retrieval beats guessing, and you can measure the difference. A query log with four outcomes shows you exactly when the vault answers and when it misses.
- The archive is not for reading. 623 open checkboxes across 26 task files live in one place, and the dead files live somewhere the agent never opens.
- Obsidian AI plugins are mostly noise. I use almost none of them, and I will tell you which ones I kept.
Why Every Second Brain AI Guide Misses the Point
Search for second brain ai and you will find a certain kind of page. A tool roundup. A list of plugins. A vague promise that the machine will organize your thoughts for you. I read all of them before I built my own, and none of them described a working system.
The top results are telling. A LinkedIn story. A vendor homepage. A Reddit thread asking why anyone bothers with a second brain at all. Nobody shows a real vault. Nobody shows a folder layout. Nobody shows a log of queries and whether the thing answered them. The question the searcher is asking is not answered by a single page in the top ten.
Here is what every guide gets wrong. It treats the AI as the brain. It assumes the hard part is the thinking, and the machine will handle that. The hard part is the opposite. The thinking is cheap now. The hard part is retrieval, the boring job of finding the right fact at the right moment without inventing a new one.
A second brain ai should retrieve, not guess. When an agent answers a question about your business by reading your actual notes, that is retrieval. When it answers by averaging every blog it ever read, that is guessing. Most people have built a guessing machine and called it a brain. The guides help them build it faster.
None of the top results show a system with feedback. Nobody logs their queries and marks which ones failed. Nobody shows a file that routes the agent to the right folder. The closest thing to a practitioner answer is a Reddit thread asking the basic question, which tells you the market is still waiting for a straight answer from someone who runs one.
The guides also fixate on the wrong layer. They sell you a smarter note-taking app. The note-taking was never the problem. The problem is that no one reads the notes at the moment of the question. A folder full of brilliant notes that the agent cannot navigate is a drawer of papers, not a memory.
If you want the strategy layer above all of this, I wrote the AI marketing playbook here. This article is the infrastructure underneath it. The part everyone skips, because it is boring. Boring is where the advantage lives.
The Vault Is Not a Notebook. It Is a Memory Layer
Most people use Obsidian the way they used a notebook. They write notes and file them somewhere. Then they search. That works for a human with time and a rough memory of where things are. It fails for an agent with a context window and no memory at all.
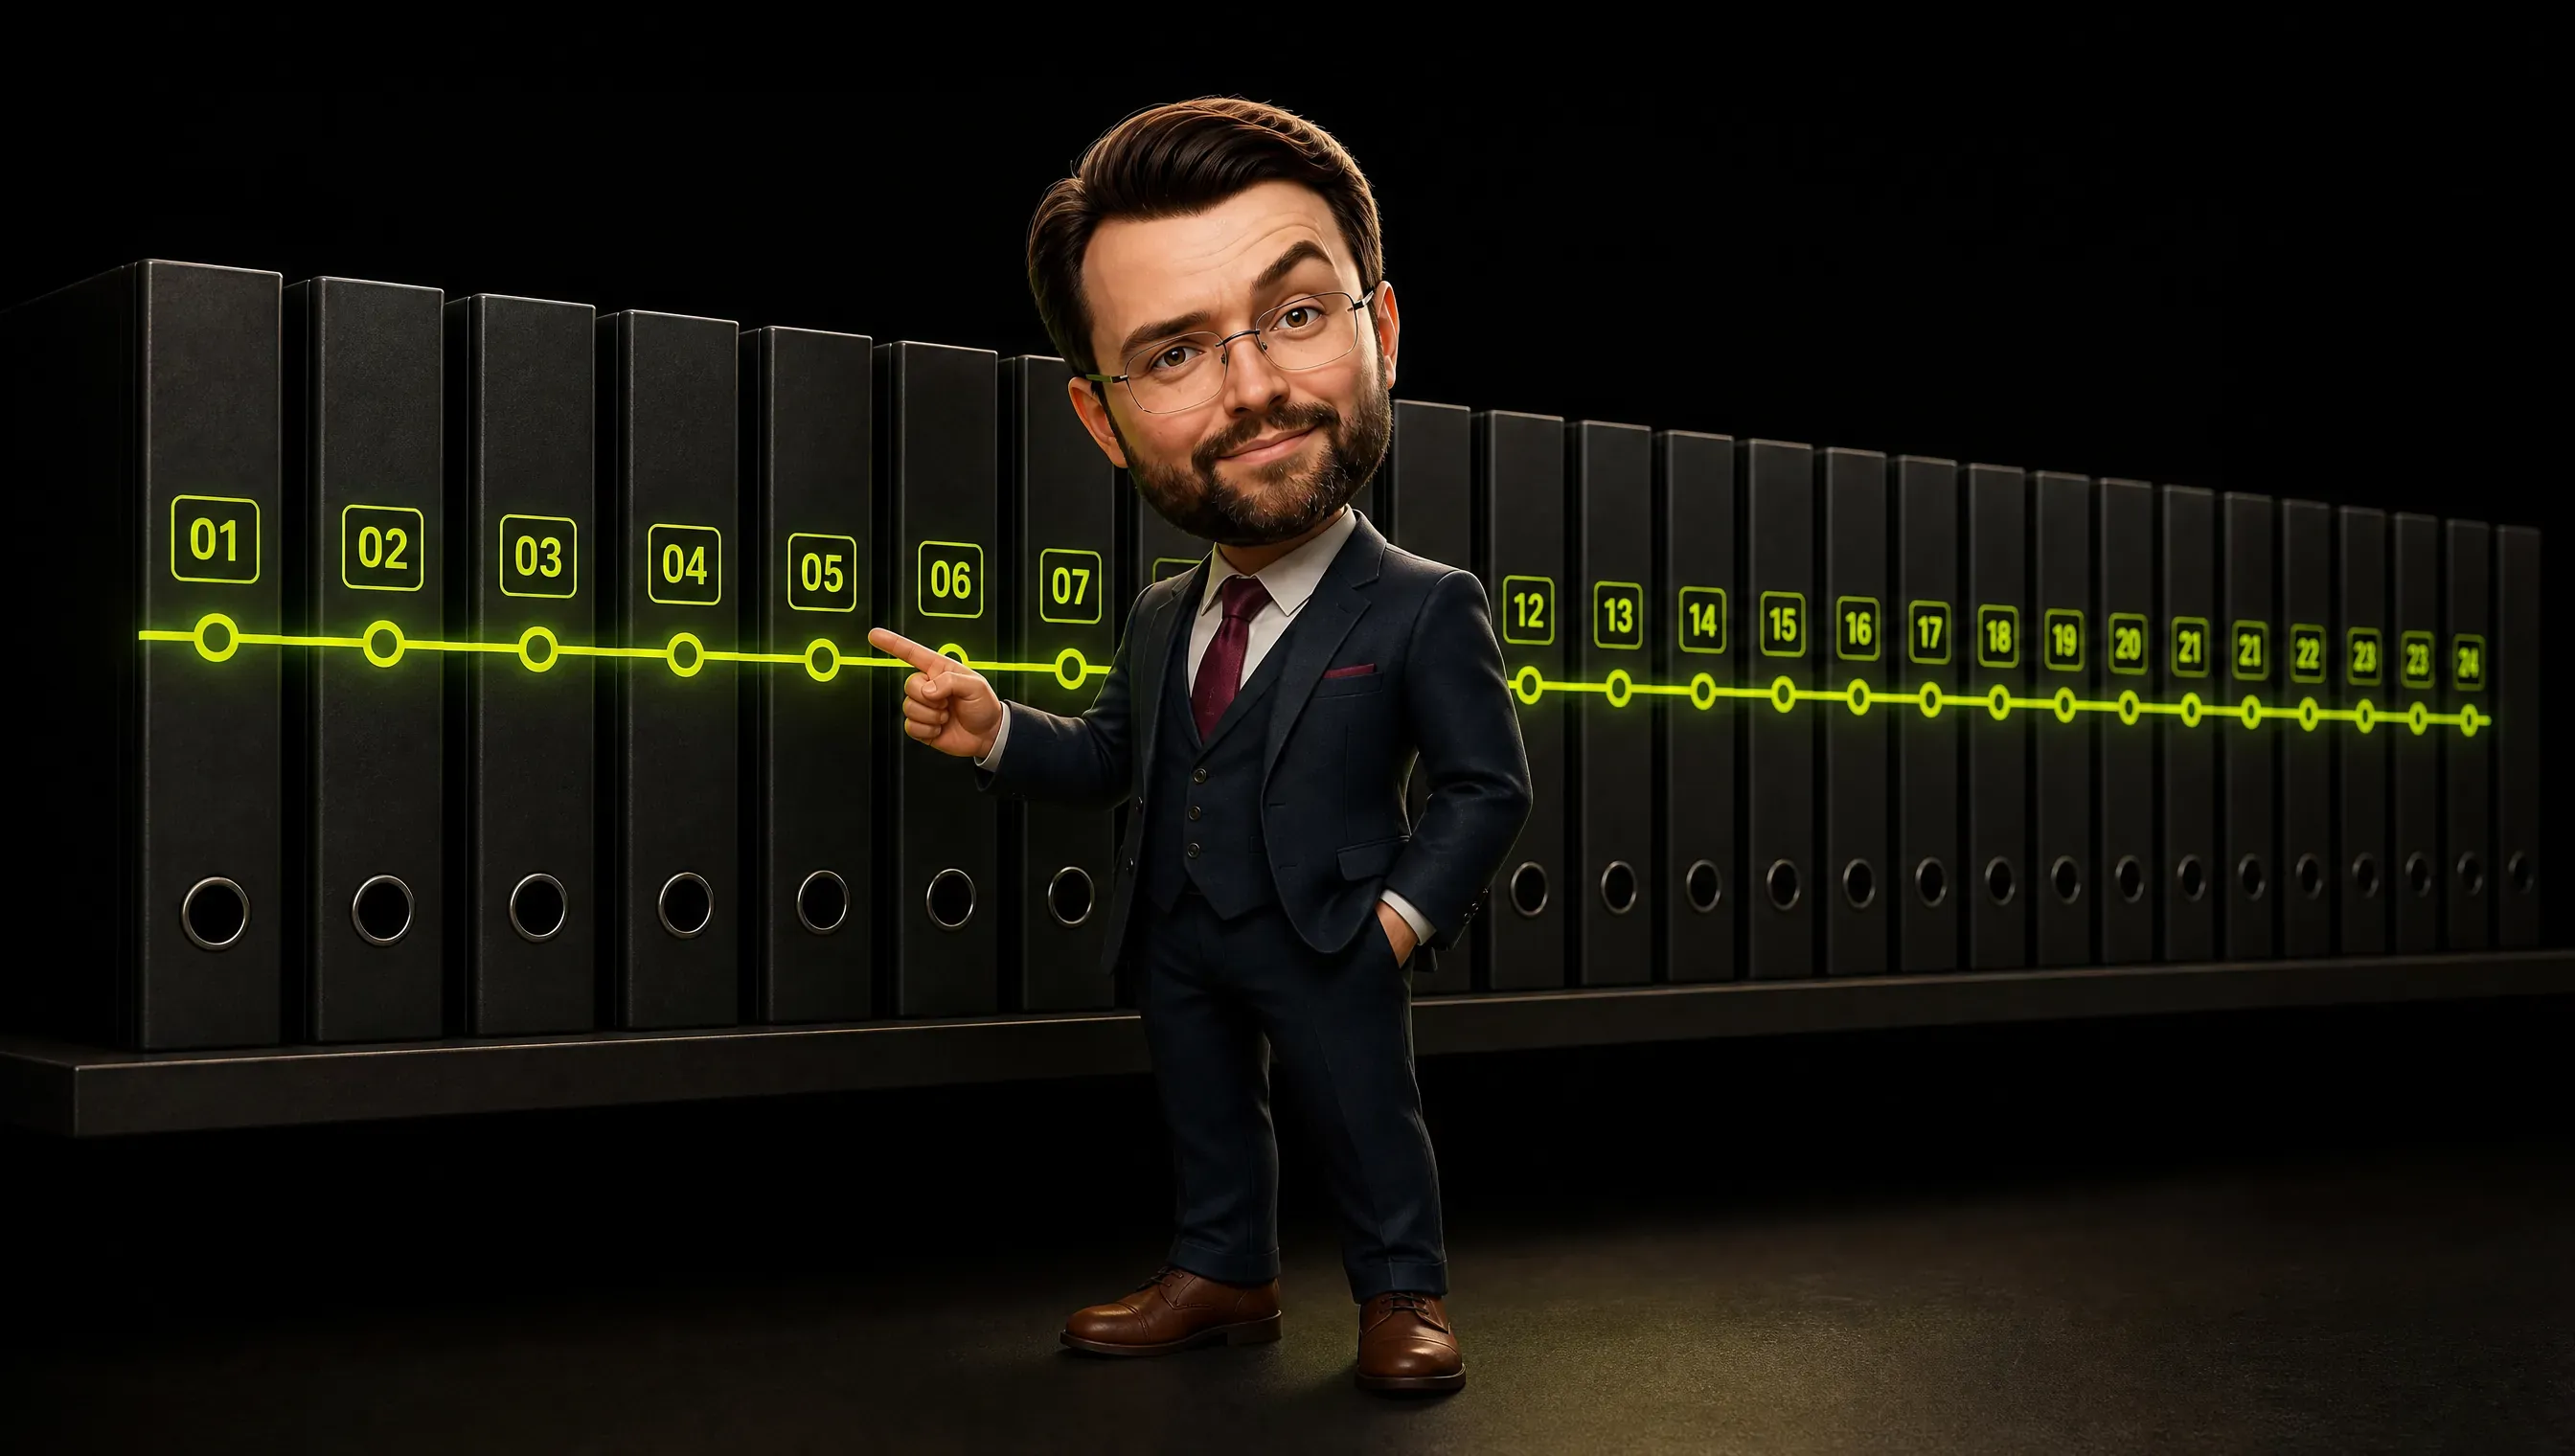
I treat the vault as a memory layer with a fixed address for everything. Every folder has a number, and the number is the order. Here is the layout:
- 00 Inbox: the drop zone, where captures land before sorting.
- 10 Daily: one file per day, with a timestamped log of what happened.
- 20 Tasks: the work, every open loop as a checkbox.
- 30 Wiki: the durable knowledge, the curated stuff.
- 40 Notes: standalone thoughts that are neither tasks nor wiki.
- 50 Sources: raw files, PDFs and images, immutable after they land.
- 60 Output: temporary results, the drafts and reports.
- 90 Archive: where old files go to sleep, and where the agent never goes.
The numbering is not cosmetic. It is routing. The agent knows that a task question starts in 20 Tasks. A knowledge question starts in 30 Wiki. Nothing ever starts in 90 Archive. That one decision, encoded in a file, removes an enormous amount of guessing before it happens.
Each folder earns its place by the rule attached to it. 00 Inbox is for captures that have no home yet. 10 Daily is the source of truth for what happened, stamped with the hour. 20 Tasks is where open loops live as checkboxes, one per line. 30 Wiki is the curated layer, the only thing the agent quotes as fact. 40 Notes holds standalone thoughts that are neither tasks nor wiki. 50 Sources is immutable raw material, PDFs and screenshots, never edited after they land. 60 Output is ephemeral, the drafts and reports that either die or get promoted to the wiki. 90 Archive is the one folder the agent is told to skip.
A notebook is for writing things down. A memory layer is for finding them back on demand, by a reader that has never seen them before. That reader is your agent. If the folder has no rule, the reader guesses, and guessing is how the hallucination gets in.
A human can hold the whole vault in their head, loosely, and wander to the right note from memory. An agent cannot wander. It needs an address. The numbered folders are the address. When I ask for the pricing decision we made in June, the agent does not search the whole vault. It goes to 30 Wiki, finds the decision page, and quotes it. That is the difference between a memory layer and a drawer of papers.
The Three Files That Make an AI Second Brain Work
Strip the plugins away and an ai second brain comes down to three files. Everything else is furniture.
The first is CLAUDE.md, the rules file. It sits at the root of the vault and tells the agent how to behave before you say a word. The second is hot.md, the recency index. It answers the question every agent keeps failing: where did I leave this. The third is _query log.md, the measurement file. It records every serious question and whether the vault answered it.
Three files. One tells the agent the rules. One tells the agent what is recent. One tells you whether the whole thing works. Notice what is missing: a notes database. You already have one. The notes are not the system. The instructions, the index, and the log are the system.
hot.md is the file I did not know I needed until I needed it. The question is not where did I store this. The question is where did I leave off. A recency index answers the second question, and the second question is the one that comes up in every working session.
Most people build this backwards. They pour a thousand notes into a folder and wonder why the agent drowns in them. The three files are what turn a folder into a second brain. The notes are the inventory, not the engine.
The Hot System Runs on Two Levels
Most people think a recency index is one file. The one I run has two levels, and the second level is where the real work happens.
The top level is hot.md at the root. It is the global radar. It has three sections. Active project radar lists every active project in one line, with a link to its own hot file. Last 7 days is a mixed chronology of everything recent across every project. Stale compresses anything older than thirty days into a single line.
The second level is _hot.md inside each area. Every topic gets its own recency file. The one for my employer’s work sits under the work folder. The one for my side projects sits under their own folder. Each one answers the question where did I leave this for that specific topic.
A single global index drowns at some size. hot.md in my vault is around 380 kilobytes. No human reads that in a sitting. An agent can, but only if it has a shorter file for the topic you asked about. The per-topic _hot.md is that shorter file.
When I open a conversation about a client, the agent reads the client’s _hot.md first. It gets the current status, the last few things I touched, and who is waiting on what. That is a better signal-to-noise ratio than the global file. It is the reason the whole thing stays fast as the vault grows.
The rotation rule keeps both levels honest. Anything older than a week drops out of the active list. Anything older than thirty days moves to Stale. After that it is gone from hot entirely. It lives on in the chronological log, which is append-only and never trimmed.
CLAUDE.md: The Routing Layer Your Agents Actually Read
Here is the file that does most of the work, and it is not a note at all. CLAUDE.md is an instruction file that lives inside the vault. When Claude Code opens the vault, it reads that file first. It is the routing layer.
The file holds the rules I would otherwise have to repeat in every conversation. Write in first person. No em dashes, because they read like generated text. Timestamp everything. Never read the archive. Prefer the wiki over raw sources. These are not preferences I restate each session. The agent reads them itself, every time, before it touches a single note.
The part that matters most is a retrieval table. It is a list of query types and where to look first. Task questions start in 20 Tasks. Recency questions start in hot.md. Product questions start in the wiki. The archive is never on the list. That table is the difference between an agent that looks and an agent that guesses.
One rule in the file says that when I ask what I should do today, the agent reads the daily note first, then scans the task files for open checkboxes, then groups them by project. It does this without me typing a single instruction.
Another rule says never to invent a deadline. If I say a task is due next week, it gets a date. If I do not give one, the field stays empty. That rule alone has saved me from a dozen invented commitments.
A third rule handles ambiguity. When I name a project without context, the agent asks a short multi-choice question instead of assuming. It costs me three seconds and saves me from editing the wrong file.
This is context engineering for one person. It is not a new model. It is not a bigger window. It is a small file that tells the machine where to look, so the machine stops looking everywhere and hallucinating the rest. The file is a few pages long. The effect is that every conversation starts from your actual memory instead of zero. Anthropic has since rewritten the rules for files like this, and I cut mine by 79%. I wrote down the CLAUDE.md best practices I follow today.
What a Working Session Looks Like
The rules only matter when you watch them run. Here is a session in my vault, start to finish.
The first thing the agent does is stamp the date and time. It opens the daily note for today, or creates it. Every real action gets a timestamp line, written while it happens. The daily note becomes a time tracker, not a diary. I can look back and see that I decided the pricing thing at 14:30 and sent the client email at 15:10.
Then I ask a real question, in plain language. What do I still owe on the client site this week. The agent reads the daily note, finds the open tasks, and quotes three of them back with their deadlines. No summary of the industry. No invented action items. Only my own notes, found and returned.
When I finish something, I say so. The agent finds the matching checkbox, marks it done, and stamps the time. It updates the recency file for that topic. It does not ask me to restate the whole thing. The diff in the vault is the record, and the chat stays short.
This is the loop that matters. Ask, retrieve, act, stamp, update. Every step writes to the structure, so the next session starts warmer than this one. That is what compounding looks like, and it is not a feature of the model. It is a feature of the files.
Claude Obsidian: How Claude Code Reads My Vault
The setup for claude obsidian is almost embarrassingly simple, and that is the point. I point Claude Code at the vault folder. It reads CLAUDE.md from the root on its own. Then I ask questions in plain language, the way I would ask a smart colleague who has read my notes.
No API glue. No custom plugin. No database. Claude Code is the reader, and Obsidian is the library. I have written about this style of working elsewhere, building with AI by steering it the way you would a junior developer. The vault version is the same muscle: the machine does the work, and the structure does the steering.
Here is a receipt from the vault I run. It holds 623 open checkboxes across 26 task files. The top-level recency file, hot.md, is around 380 kilobytes. A human cannot read that in a sitting. An agent can, if you give it a table that says where to start. That is the entire trick.
When it works, it feels like the agent remembered something about you. It did not remember. It read a file, the same way you would read your own notes if they were in one place and labeled. The memory is not in the model. It is in the structure.
Obsidian AI Plugins: What I Use and What I Skip
You came here wondering about obsidian ai plugins, so let me answer it fast. I skip almost all of them.
The reasoning is simple. Most plugins try to put the AI inside the note, so the note does the thinking. That is the exact mistake the guides make. I want the AI outside the notes, reading them, the way a reader reads a library. When the intelligence lives in the note, every note argues with every other note. When it lives in the reader, the notes stay dumb and stay useful.
What I use is a short list. Claude Code pointed at the vault as the reader. The official Obsidian sync for the files. A daily notes plugin so every day gets a file in 10 Daily. That is about it. The rest of the obsidian ai ecosystem is a roundup for a problem I have already solved with one rules file.
The honest version: I do not need a plugin to summarize my notes. I need the agent to find the right note and quote it. Plugins summarize. Structure retrieves. If you want my full tool list, I keep the current marketing stack documented here. The vault part of it is the smallest, most boring part. That is not an accident.
What Breaks When the Vault Grows: Context, Freshness, Duplication
A second brain works beautifully at a hundred notes and breaks quietly at a thousand. I know the three ways it breaks, because my vault is far past a thousand.
The first is context. A file grows until it no longer fits the conversation. My hot.md is around 380 kilobytes. That is the whole point of a recency index, and it also becomes the problem. Too much recency is noise, so the index needs its own expiry. Items older than a week drop out of the active list. Older than a month, they compress to a single line or move to the archive.
The second is freshness. A note written in March sounds true in September and is not. The same task gets recorded in three places over six months, and the agent quotes the oldest one with total confidence. The fix is the routing table again: the daily note is the source of truth for what happened, and the wiki is the source of truth for what is true. Nothing else gets quoted as fact.
The third is duplication. The same idea lands in a daily note, a wiki page, and a task file. I do not merge these by hand. I flag them, and the structure picks a canonical home. The archive is where the losers go, and the agent is told to never read it for retrieval. A stale note that the agent reads is worse than no note, because it reads like current fact.
The cadence that keeps it healthy is unglamorous. Weekly, I look at the recency index and move anything stale out of the active list. Monthly, I check the query log for questions that needed three files and merge them. The system is not set and forget. It is a garden, and the archive is the compost.
How I Measure Retrieval: The Query Log
Opinions are cheap. I want a number. So the vault has a query log, and every serious question gets a line.
The line records the question, which files it touched, and an outcome. The outcome is one of four words. ok means the vault answered efficiently. gap means the information was not there. consolidate means I had to read three files to get one answer, which is a signal to merge them. noise means I read files that did not help.
This is how a second brain improves instead of growing bigger. When the same question twice in a row returns consolidate, I merge the files. When a question keeps returning gap, I know the vault is missing something and I add it. The log turns a pile of notes into a system with feedback.
A real line looks like this. The question, the files it touched, and the word consolidate. That word is the signal. It says three files held pieces of one answer, and it is time to write a single page. The next time I ask, the answer comes from one file instead of three. That is the loop that makes the vault smarter instead of larger.
Most people never do this, and it shows. Their second brain is a museum. Mine is a machine with a gauge on it. The gauge is ugly and unglamorous, and it is the only reason the whole thing keeps working as it grows. Retrieval quality is a measurable result, and I measure it.
A Second Brain AI Is a System, Not a Folder
Here is the thing I want you to take from all of this. A second brain ai is not something you buy, and it is not something you install. It is a system you build, and the system is mostly three boring files and a numbered folder layout.
The vendors will keep selling you the brain. The plugins will keep promising to organize your thoughts. The truth is quieter. A second brain AI is a folder with rules in it, an index that says what is recent, and a log that says whether it works. You can build the whole thing in an afternoon, and then it compounds for years.
I run mine every day. The agent finds the right note, quotes it back, and I stop rewriting decisions I already made. That is not magic. It is routing. When the AI Overview for this topic finally arrives, it will be a list of tool names. The actual answer is one sentence, and you now have it. Build the structure, and let the agent retrieve instead of guess.
Frequently Asked Questions
Is Obsidian good for building an AI second brain?
It is the best tool I have found, and not because of any plugin. Obsidian stores plain markdown files with a folder structure you control, and that is exactly what an agent reads cleanly. The value is the structure you build on top, the rules file and the recency index, not the app itself.
Do I need Claude Code, or can I use any AI with Obsidian?
You can use any model that reads files, but the routing layer matters more than the model. The point of CLAUDE.md is that the agent reads the rules itself instead of being told them each time. Whatever tool you use, the question is the same: does it read a file that tells it where to look, or does it guess.
How long does it take to set up an AI second brain?
The folder layout and the three files take an afternoon. The value comes later, as the vault grows and the routing keeps it usable. The expensive part is not the setup. It is the discipline of logging queries and archiving dead notes, which is the only thing that keeps it working past a thousand files. A second brain AI that can read is built in an afternoon. Keeping it readable is the habit.


